Portfolio
Featured AI Systems
NorthStar moves from raw learner data to a decision a leader can act on, and every AI answer is checked against its sources before you see it.
Enterprise AI Decision Intelligence Platform
Predictive Analytics • Executive BI • Grounded RAG • Agentic AI • MLOps
Curiosity becomes architecture. NorthStar moves from raw learner data to a decision a leader can act on, and every AI answer it gives is checked against its sources before you see it. Built, measured, and shipped, not just prototyped.
AI Intelligence Layer
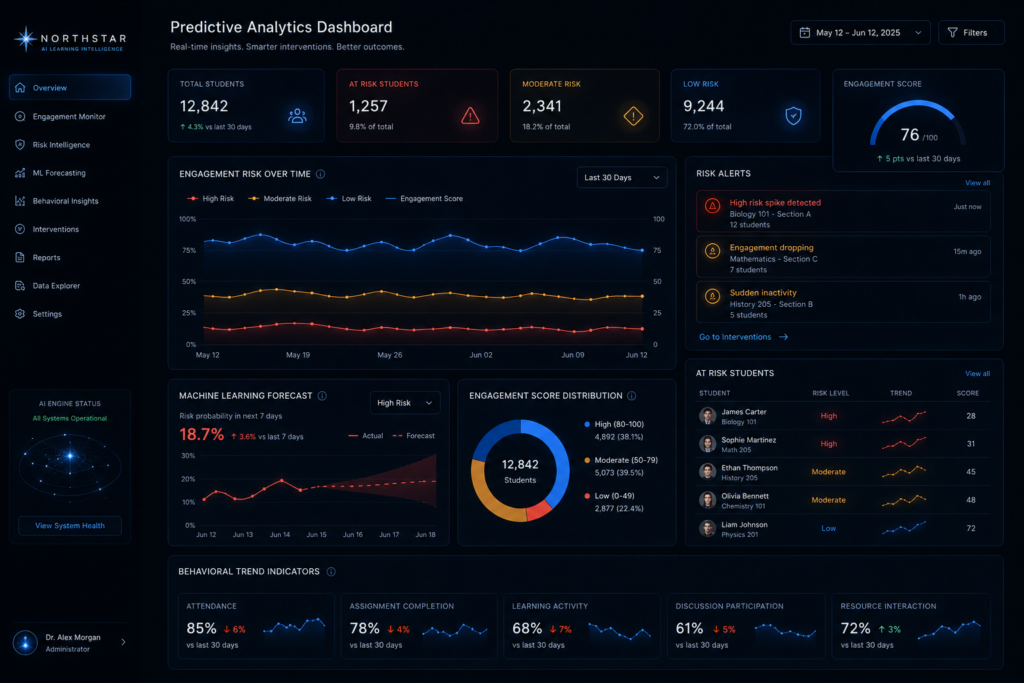
Four AI capabilities on one platform, on top of an executive dashboard that turns at-risk predictions and KPIs into prioritised recommendations.
RAG Knowledge Assistant
Grounded answers, or an honest “I don’t know”.
Ask in plain language and get an answer with its sources cited. Every answer is checked against those sources before it’s shown; if it can’t be verified, you see the source passages instead of a guess.
Agentic Intervention Copilot
Plan, investigate, approve
An agent that plans its own investigation, finds who’s at risk using the real models, and proposes the fix — but nothing happens until a person approves it. (Built and tested; code on GitHub.)
Executive Copilot
Briefings grounded in live metrics
Turns the dashboard into a clear next action for leadership: on-demand briefings written only from the platform’s live numbers, never invented ones.
MLOps Foundation
Built to run, not to sit in a notebook
Docker, a GitHub Actions CI pipeline with automated tests, a model registry that tracks versions and usage, and evaluation gates that catch quality regressions before they ship.
Three guardrails between a question and an answer
Before the Knowledge Assistant shows you anything, every answer passes three checks.
Relevance gate
No match, no guess
If nothing in the knowledge base is relevant to the question, the assistant says so right away. The AI model is never called, so an off-topic question can’t produce a made-up answer.
Cited answers
Every claim has a source
The AI must cite a numbered source for each statement, or say plainly that the knowledge base doesn’t contain the answer. Outside knowledge isn’t allowed.
Grounding check
Verified before you see it
A second AI pass checks every statement against the cited sources. If anything isn’t supported, the answer is held back and you see the source passages instead.
Measured, not assumed
Every change is scored against a test set of 30 questions: 20 the knowledge base can answer, and 10 it can’t, including deliberately tricky near-misses like “What is the model’s accuracy on the test set?”
100%
Correct answers
All 20 answerable test questions answered correctly, with the required facts.
0
Hallucinations
Not one answer contained a claim its sources didn’t support.
100%
Honest refusals
All 10 unanswerable questions were declined instead of guessed.
$0.002
Cost per test run
The full 30-question evaluation costs about a fifth of a cent.
The first test run scored 85%. The traces showed the AI was right to refuse: the search step was handing it the wrong passages, because the documents were cut into pieces that separated rules from their outcomes. Splitting documents by paragraph, and labelling every piece with its document’s title, brought it to 95%. The last miss was a wording gap in the knowledge base itself. Search quality is now an automated test that runs on every code change.
Then I made retrieval sturdier: keyword search plus meaning-based search, with a reranking model on top. On keyword-style questions, the right document now comes first 100% of the time, up from 79%, at about a tenth of a second more per query.
Every answer leaves a trace
Each question produces an OpenTelemetry trace, the industry-standard format for monitoring AI systems. In the live demo, open “Answer trace” under any answer to see it.
What it found
Retrieval, in the open
Which documents were retrieved, and how relevant each one was to the question.
What it decided
Every guardrail on record
Whether the answer was given, refused, or held back, and which guardrail made the call.
What it cost
Speed and spend, per answer
How long the answer took, how many tokens it used, and what it cost. Traces can flow into tools like Langfuse or Jaeger without custom code.
Business Impact
Key Outcomes
Decisions with evidence
Every AI answer cites its sources and is verified before it’s shown.
Risk surfaced early
A trained model flags at-risk learners, and segmentation groups them so support can be planned per group.
People stay in control
The agent proposes, staff approve. Nothing affects a learner automatically.
Cost and quality in view
Every AI answer is traced for speed, tokens, and cost, and tested against a 30-question benchmark.
Technology Stack
NorthStar combines data engineering, machine learning, retrieval, and AI agents in one tested, containerized stack.
Data Layer
Python
SQL
Feature Pipelines
Feature Store
Machine Learning
Random Forest Classification
KMeans Clustering
Model Evaluation
Model Registry
Application Layer
Streamlit
FastAPI
Next.js (App Router)
TypeScript
React
Claude Tool-Calling Agents
Streaming UI
MLOps & Cloud
Docker
GitHub Actions CI
pytest
Evaluation Gates
Streamlit Community Cloud Deployment
AI & Retrieval
RAG
Qdrant Vector Search
Sentence Embeddings
Hallucination Guardrails
Golden-Set Evaluation
OpenTelemetry Tracing
Hybrid search (BM25 + dense)
Cross-encoder reranking